Deep Dives · Agentic AI
Agentic AI Architecture Patterns: Single-agent, Multi-agent, Hierarchical, Swarm
The four patterns that matter in production, with the cost, debuggability and quality trade-offs of each, and where each one breaks.
Four patterns at a glance
1. Single-agent + tools
One LLM, a fixed toolset
2. Multi-agent peers
Agents critique each other
3. Hierarchical
Manager dispatches specialists
4. Swarm
Many agents, shared memory
Picking the right agentic architecture is the highest-leverage decision in any agent project. Get it wrong and you waste tokens, hit infinite loops, or ship a system that's impossible to debug. This is a practitioner's tour of the four patterns that matter — and where each one breaks. It's also the lens we use in the CAASA agentic AI certification to teach architectural decision-making.
1. Single-agent + Tools
One LLM, a fixed toolset, a ReAct or function-calling loop. Best for narrow tasks: a code-fix bot, a Q&A agent, an email triager.
The task is narrow and scripted. It is simple, cheap and easy to debug.
Goals become open-ended, or long contexts cause attention drift.
Frameworks: LangGraph (linear graph), OpenAI Agents SDK
2. Multi-agent (Peer Collaboration)
Several agents with overlapping or distinct roles converse to solve a problem. The classic example is researcher, writer and reviewer for content generation.
Open-ended tasks benefit from critique loops between agents.
Token cost balloons, coordination overhead grows and runs become non-deterministic.
Frameworks: AutoGen, CrewAI
3. Hierarchical (Manager → Specialists)
A manager agent decomposes the goal and dispatches sub-tasks to specialist agents, each with a focused toolset, then aggregates and decides the next step. This is the dominant 2026 pattern for enterprise.
You need explicit control flow, isolated failures, predictable cost ceilings and easier observability.
The manager becomes a bottleneck, or its planning prompt is poorly designed.
Frameworks: LangGraph (subgraphs), AutoGen (GroupChatManager)
4. Swarm
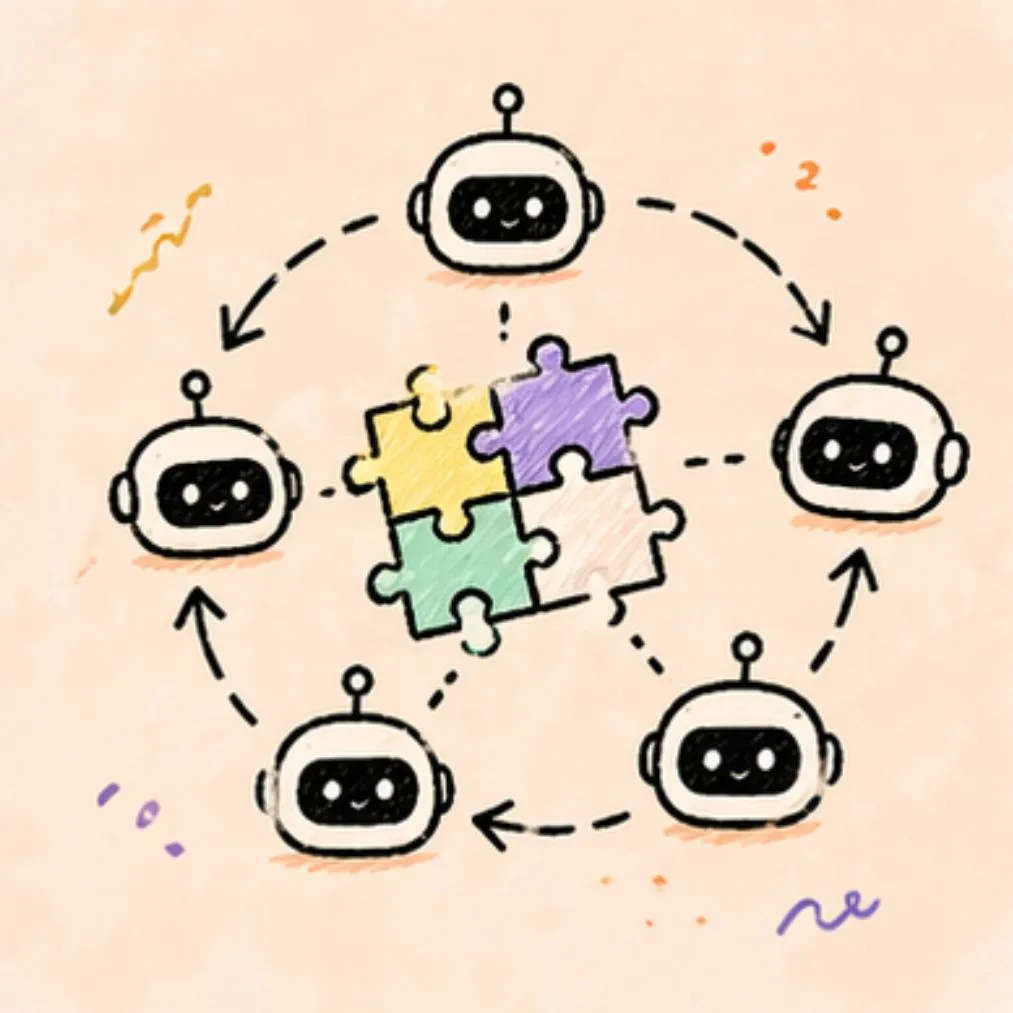
Many lightweight agents act in parallel with shared blackboard memory, inspired by ant-colony optimisation. Useful for exploration: parallel hypothesis testing and distributed research.
Work is genuinely parallel, and robustness to single-agent failure matters.
Coordination is hard, convergence is not guaranteed and observability is brutal.
Frameworks: Custom orchestration, AutoGen with parallel groups
 Hands-on course · 3 hrsArchitectural Patterns in CrewAI and AutogenBuild these patterns with an instructor →
Decision Matrix
The four patterns side by side. More pips on cost is more expensive; more pips on debuggability is easier to debug.
| Pattern | Task Type | Cost | Debuggability | Quality Ceiling |
|---|---|---|---|---|
| Single-agent | Narrow / scripted | Medium | ||
| Multi-agent | Open-ended creative | High | ||
| Hierarchical | Enterprise workflows | High | ||
| Swarm | Exploration / R&D | Variable |
Cross-cutting Concerns
Whichever pattern you pick, you still need these six controls. They are non-negotiable in production and form a major part of any serious agentic AI certification.
- 01Structured-output enforcement (Pydantic + JSON schema)
- 02Retry and backoff
- 03Tool allow-lists
- 04Prompt-injection defences on tool outputs
- 05Budget caps per request
- 06Full traces (LangSmith / OpenTelemetry)
How to Choose
Do not default to multi-agent because it sounds sophisticated. It is usually three times the cost for the same outcome.
Conclusion
Architecture is the leverage point. Master the four patterns, know when each breaks, and instrument everything. To get structured, exam-validated training on these patterns plus the surrounding production concerns, the ADaSci agentic AI certification (CAASA) is purpose-built for this curriculum.
- Agentic AI
- AutoGen
- CrewAI