Deep Dives
DSPy Prompt Optimization: A Hands-On Guide with Examples
A hands-on guide to DSPy prompt optimization: signatures, modules and optimizers, with worked examples that tune LLM prompts automatically.

In the evolving landscape of large language models (LLMs), optimizing prompts and model behavior is often crucial but labor-intensive. Traditional approaches require breaking down problems manually, tuning prompts step-by-step, and iteratively refining synthetic data for fine tuning—all of which can become chaotic when changes are introduced. Enter DSPy, a framework designed to make this process systematic and powerful by separating the program’s structure from its LLM parameters.
DSPy introduces LM-driven optimizers that automatically adjust prompts and weights based on defined metrics, creating reliable and adaptable LLM pipelines. Similar to how frameworks like PyTorch manage neural network parameters, DSPy offers modules and optimizers that eliminate manual prompt-tweaking, allowing developers to focus on building high-quality systems without wrestling with repetitive prompt engineering. In this blog, we’ll explore how DSPy transforms prompt and parameter optimization for LLMs, making it less cumbersome and more impactful.
Let’s start with understanding DSPy in depth.
Understanding DSPy for Optimizing Language Model Workflows
The concept behind DSPy addresses a core issue in developing robust language model (LM) pipelines which is optimizing prompts and LM parameters separately from the programming logic. By introducing a “signature” system that encapsulates prompt best practices, DSPy aims to make prompt engineering both modular and systematic. Imagine a Retrieval-Augmented Generation (RAG) workflow, where prompt adjustments are typically done manually to improve accuracy. DSPy removes the burden of managing prompt engineering within code, instead letting developers focus on system logic while DSPy handles automatic prompt refinements and adjustments.
In essence, DSPy allows you to set high-level assertions and configurations, which it then optimizes automatically. For instance, in a binary question-answering task, rather than manually adjusting prompts to ensure binary responses, DSPy lets you assert that the answer should only be “yes” or “no.” If the LM deviates, DSPy backtracks and re-optimizes the prompt automatically to guide the model toward the desired output. Similarly, DSPy facilitates complex multi-step retrieval processes without the need for intricate prompt engineering, making it a powerful tool for building flexible LM pipelines.
However, DSPy as a framework is still evolving. Although the concept is promising, the current implementation has notable limitations: it lacks production readiness, has a steep learning curve due to its heavy reliance on meta-programming, and suffers from inadequate documentation. While DSPy simplifies prompt optimization theoretically, the code complexity can be a significant hurdle for users.
Overview of DSPy Workflow
DSPy employs a logical, five-step workflow tailored for language tasks, streamlining the process from data preparation to evaluation.
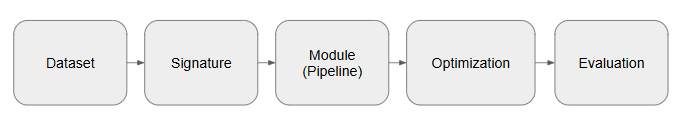
DSPy’s Workflow begins with the Dataset stage, where training data, such as blog posts, Q&A pairs, or other text data, is prepared and structured. The next step, Signature, establishes an input-output contract, clearly defining the task’s expected inputs and outputs. The Module (Pipeline) stage follows, where DSPy combines various operators to execute specific tasks, such as content generation or text analysis. In the Optimization phase, DSPy automatically fine-tunes parameters and prompts to enhance pipeline performance. Finally, Evaluation assesses pipeline effectiveness using metrics like accuracy and quality. This structured approach is very effective for various tasks, including content generation and automated content enhancement.
Hands-on Implementation of DSPy
Step 1: Setting up the environment
First, we’ll set up our development environment by installing necessary packages, configuring paths, and importing required libraries. This setup is specifically designed to work in Google Colab.
Step 2: Configuring LM and RM
Now we’ll configure our Language Model (GPT-3.5-turbo) and Retrieval Model (ColBERTv2). These will form the backbone of our RAG system.
Step 3: Loading the dataset
We’ll use the HotpotQA dataset for training and evaluation. We’ll load a small subset for training (20 examples) and development (50 examples). This dataset consists of questions and answers
Step 4: Building Signatures
Signatures in DSPy define the interface for our LM calls. Here we’ll create a signature for generating answers that specifies input/output fields and their descriptions.
Step 5: Building the Pipeline
Let’s create our RAG pipeline by combining retrieval and answer generation into a single module. This pipeline will retrieve relevant passages and generate answers.
Step 6: Optimizing the Pipeline
Using DSPy’s Teleprompter, we’ll optimize our pipeline by automatically learning effective prompts for its modules through few-shot learning.
Step 7: Executing the Pipeline
Now we can test our optimized RAG system with a sample question to see how it performs in practice.
Step 8: Evaluating the Pipeline
Let’s evaluate our pipeline’s overall performance using exact match metrics on our development set.
Step 9: Evaluating the Retrieval
Finally, we’ll specifically evaluate the retrieval component by checking if our system finds the gold (correct) passages for each question.
Output –

Final Words
In summary, DSPy presents a promising approach to optimizing complex language model workflows by separating prompt engineering from programming logic, bringing structure and automation to what is traditionally a manual, iterative process. While the framework is still evolving and has some limitations, its foundational ideas—like automatic prompt adjustments, module settings, and assertion-based backtracking—are innovative steps towards a more robust and scalable way to develop LM-based applications. DSPy simplifies the integration of LLMs into pipelines, making it easier to experiment, refine, and deploy, especially as the tool matures and becomes more production-ready.
References
Go further: engineer generative AI applications
Prompt optimization is one part of building reliable LLM applications. The Certified Generative AI Engineer (CGAE) credential examines the full set of skills, from prompting and retrieval to evaluation and deployment.